WAN 3.0, tested on how a line is said
MXVDXN's first test of any new video model is language nuance. WAN 3.0 gets a dialogue scene, not a landscape. He paid for the run himself, via Venice.
Whenever MXVDXN tests a new video model, the first question is language nuance. WAN 3.0 gets a scene where how something is said matters, and his verdict is that it did pretty well. He ran it through Venice, with his own money, and he says so because the disclaimer matters to him.
Nuance is a better benchmark than a dragon because you cannot grade it by resolution. A line lands or it glances off. Faces, pauses, and the sense that two people are in the same conversation are the whole test, and they are exactly what spectacle prompts are designed to avoid.
The post is a method as much as a clip. This is how he decides whether a model can be trusted with a scene that has a point.
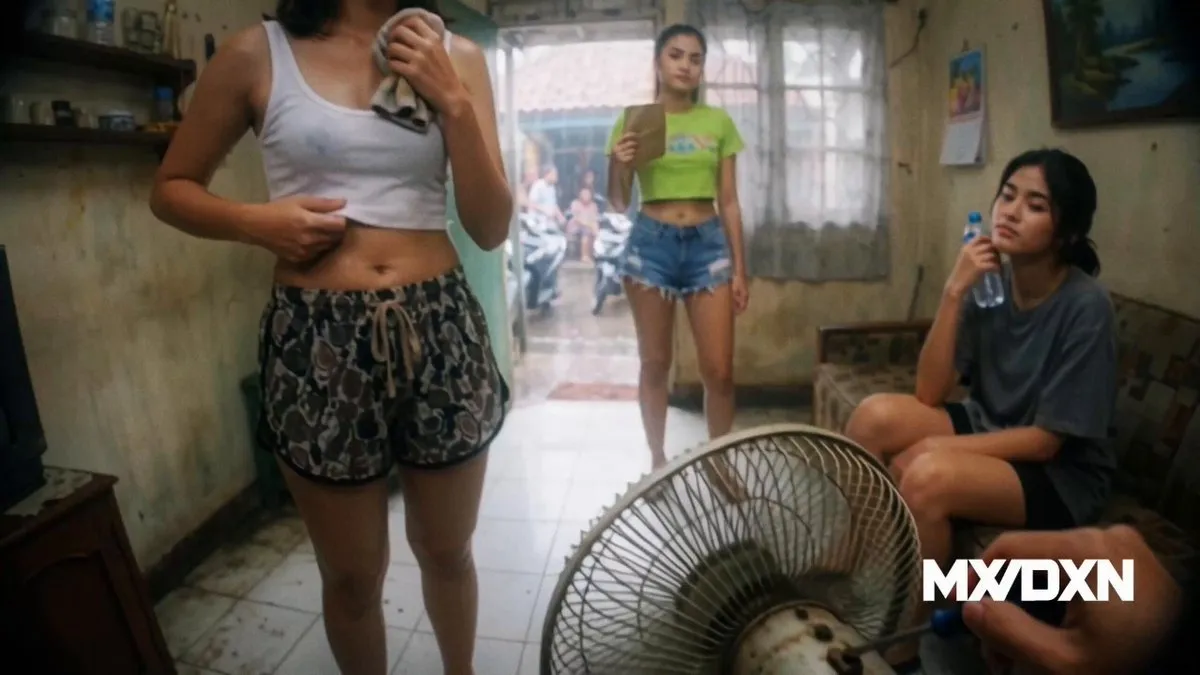
MXVDXN // DAN
@mxvdxn
Okay! WAN 3.0 let's go! Whenever I test a new video model, the first thing I always do is test how well it handles language nuance. And yup, WAN 3.0 did it pretty well. I tested it via @AskVenice And nope, this is not sponsored content. I use my own money. I’ve always used https://t.co/yoGIRNzxWo
2.6K likes
- likes
- 2,593
- replies
- 3
Captured when this was curated, not live. —